# @title Auxiliary: attention figures
def attention_grid(ax, values, row_labels, column_labels, title, blocked=None, probabilities=False):
    shown = np.where(np.isfinite(values), values, 0)
    ax.imshow(shown, cmap="Blues" if probabilities else "RdBu_r",
              vmin=0 if probabilities else -max(abs(shown).max(), 1),
              vmax=1 if probabilities else max(abs(shown).max(), 1), aspect="auto")
    for t in range(values.shape[0]):
        for j in range(values.shape[1]):
            text = "blocked" if blocked is not None and blocked[t,j] else f"{values[t,j]:.2f}"
            is_blocked = blocked is not None and blocked[t,j]
            dark = values[t,j] > .6 if probabilities else abs(values[t,j]) > .65*max(abs(shown).max(), 1)
            color = "white" if dark and not is_blocked else NAVY
            ax.text(j, t, text, ha="center", va="center", fontsize=9, color=color)
    ax.set(xticks=range(len(column_labels)), xticklabels=column_labels,
           yticks=range(len(row_labels)), yticklabels=row_labels, title=title)
    ax.tick_params(axis="x", labelrotation=45)

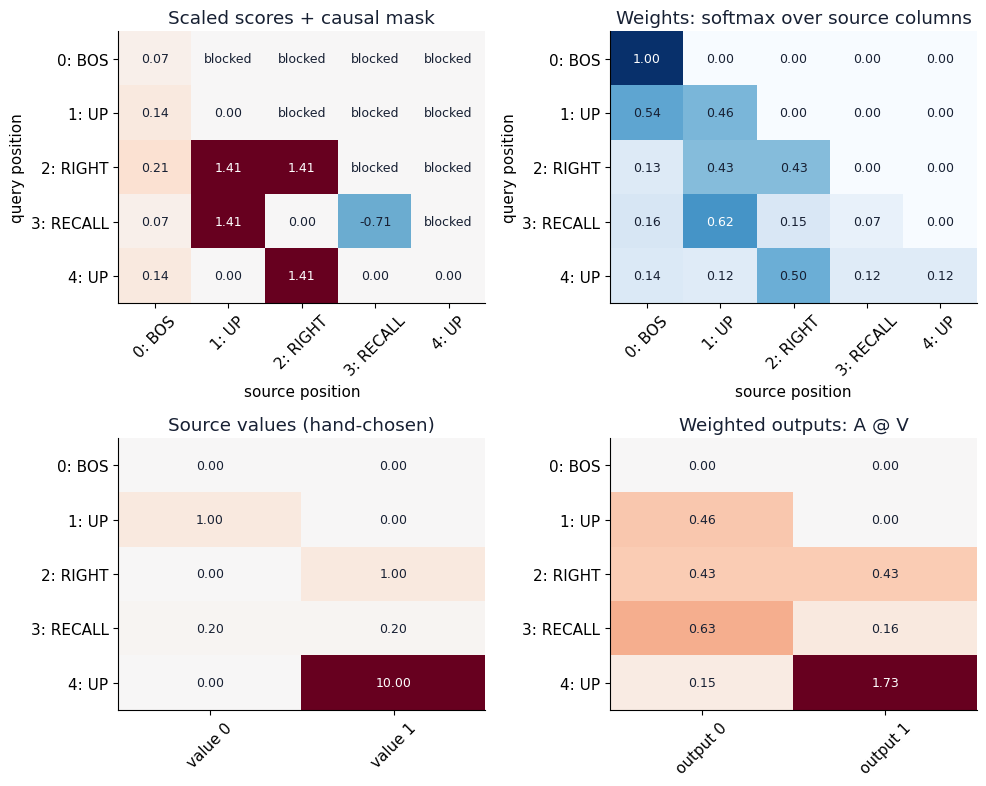
def plot_attention_calculation():
    labels = [f"{t}: {TOKENS[token]}" for t,token in enumerate(attention_tokens)]
    fig, axes = plt.subplots(2, 2, figsize=(10, 8))
    attention_grid(axes[0,0], masked_scores_demo, labels, labels, "Scaled scores + causal mask", future_mask_demo)
    attention_grid(axes[0,1], weights_demo, labels, labels, "Weights: softmax over source columns", probabilities=True)
    attention_grid(axes[1,0], V_demo, labels, ["value 0", "value 1"], "Source values (hand-chosen)")
    attention_grid(axes[1,1], output_demo, labels, ["output 0", "output 1"], "Weighted outputs: A @ V")
    for ax in axes[0]: ax.set_ylabel("query position"); ax.set_xlabel("source position")
    fig.tight_layout(); save_figure(fig, "12-attention-calculation"); plt.show()

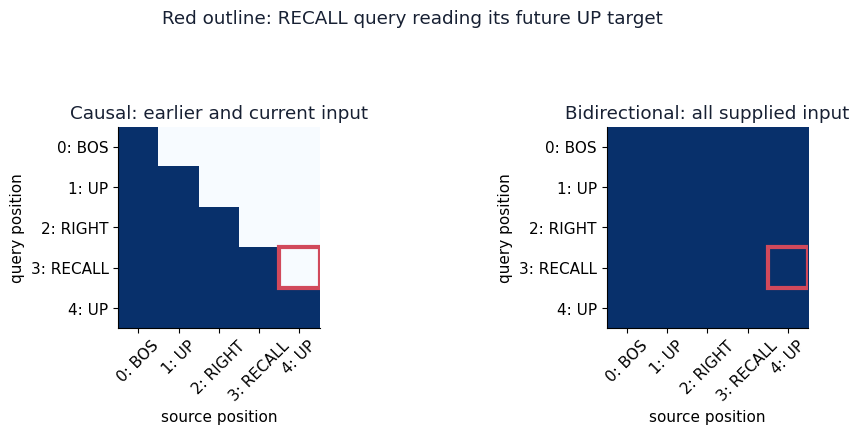
def plot_mask_comparison():
    labels = [f"{t}: {TOKENS[token]}" for t,token in enumerate(attention_tokens)]
    fig, axes = plt.subplots(1, 2, figsize=(10, 4.4))
    for ax, allowed, title in zip(axes, (~future_mask_demo, np.ones((5,5), dtype=bool)),
                                  ("Causal: earlier and current input", "Bidirectional: all supplied input")):
        ax.imshow(allowed, cmap="Blues", vmin=0, vmax=1)
        ax.set(xticks=range(5), xticklabels=labels, yticks=range(5), yticklabels=labels,
               xlabel="source position", ylabel="query position", title=title)
        ax.tick_params(axis="x", labelrotation=45)
        ax.add_patch(plt.Rectangle((3.5, 2.5), 1, 1, fill=False, ec="#d1495b", lw=3))
    fig.suptitle("Red outline: RECALL query reading its future UP target", color=NAVY)
    fig.tight_layout(rect=(0, 0, 1, .88)); save_figure(fig, "13-causal-bidirectional-masks"); plt.show()

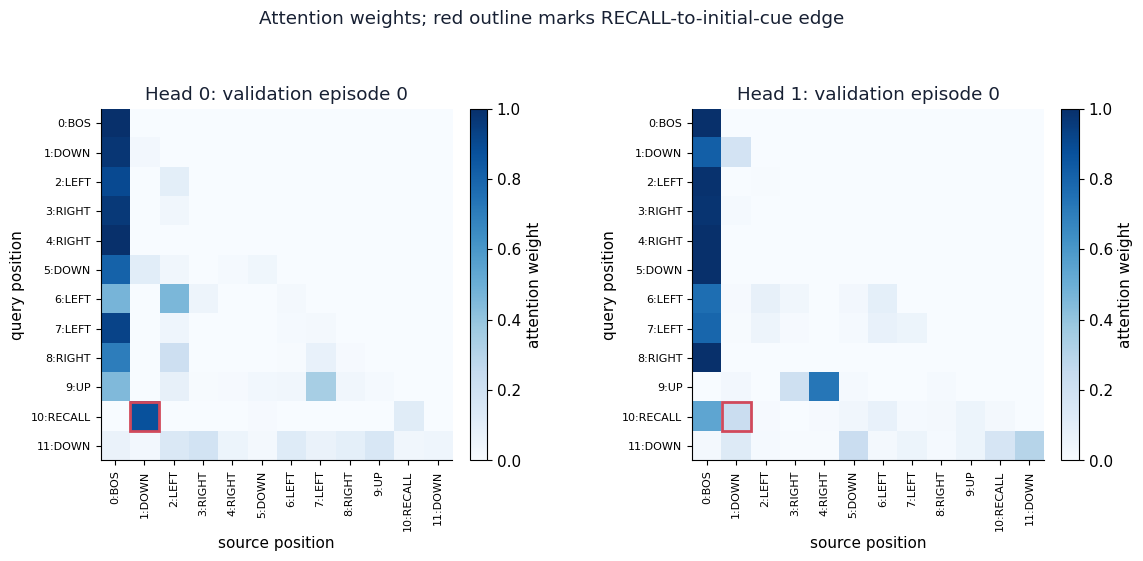
def plot_trained_attention(model, ids):
    model.eval()
    with torch.no_grad():
        _, weights = model(ids[:1], return_attention=True)
    weights = weights[0].numpy()
    labels = [f"{t}:{TOKENS[int(token)]}" for t,token in enumerate(ids[0])]
    fig, axes = plt.subplots(1, 2, figsize=(12, 5.5))
    for head, ax in enumerate(axes):
        image = ax.imshow(weights[head], cmap="Blues", vmin=0, vmax=1)
        fig.colorbar(image, ax=ax, fraction=.046, pad=.04, label="attention weight")
        ax.set(xticks=range(len(labels)), xticklabels=labels, yticks=range(len(labels)), yticklabels=labels,
               xlabel="source position", ylabel="query position", title=f"Head {head}: validation episode 0")
        ax.tick_params(axis="x", labelrotation=90, labelsize=8); ax.tick_params(axis="y", labelsize=8)
        ax.add_patch(plt.Rectangle((.5, 9.5), 1, 1, fill=False, ec="#d1495b", lw=2))
    fig.suptitle("Attention weights; red outline marks RECALL-to-initial-cue edge", color=NAVY)
    fig.tight_layout(rect=(0, 0, 1, .90)); save_figure(fig, "16-transformer-attention"); plt.show()

def teaching_box(ax, x, y, w, h, text):
    from matplotlib.patches import FancyBboxPatch
    ax.add_patch(FancyBboxPatch((x,y),w,h,boxstyle="round,pad=.07",
                               facecolor="#eef3ff",edgecolor=BLUE))
    ax.text(x+w/2,y+h/2,text,ha="center",va="center",color=NAVY,fontsize=12)

def teaching_arrow(ax, start, end):
    ax.annotate("",xy=end,xytext=start,
                arrowprops=dict(arrowstyle="->",color=GRAY,lw=1.6))

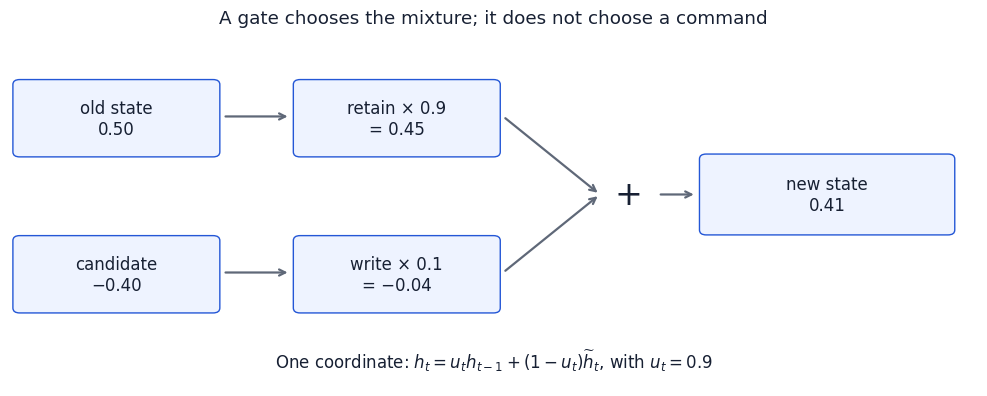
def plot_gru_carry():
    fig,ax=plt.subplots(figsize=(10,4.1));ax.set(xlim=(0,10),ylim=(0,5));ax.axis("off")
    teaching_box(ax,.1,3.3,2.0,.95,"old state\n0.50")
    teaching_box(ax,.1,1.1,2.0,.95,"candidate\n−0.40")
    teaching_box(ax,3.0,3.3,2.0,.95,"retain × 0.9\n= 0.45")
    teaching_box(ax,3.0,1.1,2.0,.95,"write × 0.1\n= −0.04")
    teaching_box(ax,7.2,2.2,2.5,1.0,"new state\n0.41")
    teaching_arrow(ax,(2.2,3.8),(2.9,3.8));teaching_arrow(ax,(2.2,1.6),(2.9,1.6))
    teaching_arrow(ax,(5.1,3.8),(6.1,2.7));teaching_arrow(ax,(5.1,1.6),(6.1,2.7))
    ax.text(6.4,2.7,"+",fontsize=24,ha="center",va="center",color=NAVY)
    teaching_arrow(ax,(6.7,2.7),(7.1,2.7))
    ax.text(5,.25,r"One coordinate: $h_t=u_t h_{t-1}+(1-u_t)\widetilde h_t$, with $u_t=0.9$",
            ha="center",color=NAVY,fontsize=12)
    ax.set_title("A gate chooses the mixture; it does not choose a command",color=NAVY)
    fig.tight_layout();save_figure(fig,"21-gru-carry-mixture");plt.show()

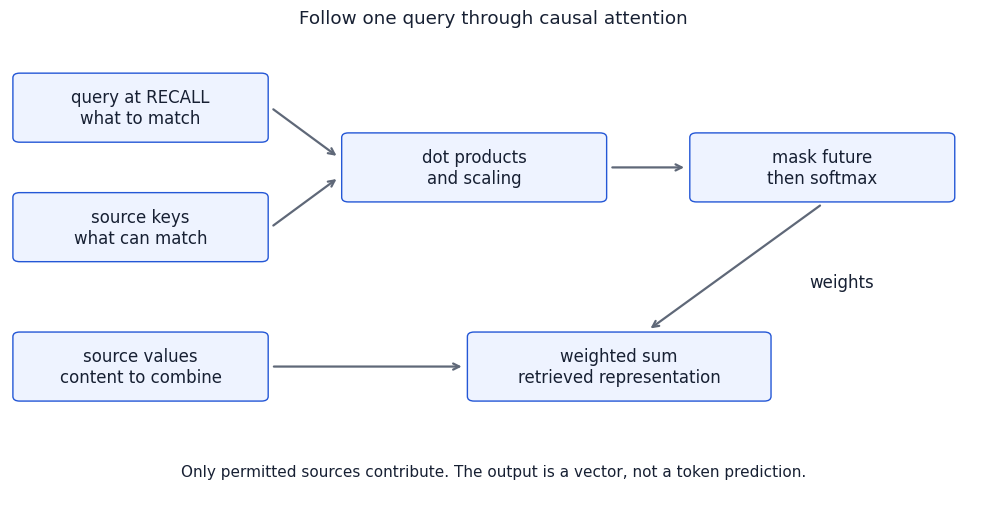
def plot_attention_route():
    fig,ax=plt.subplots(figsize=(10,5.2));ax.set(xlim=(0,10),ylim=(0,7));ax.axis("off")
    teaching_box(ax,.1,5.4,2.5,.9,"query at RECALL\nwhat to match")
    teaching_box(ax,.1,3.6,2.5,.9,"source keys\nwhat can match")
    teaching_box(ax,3.5,4.5,2.6,.9,"dot products\nand scaling")
    teaching_arrow(ax,(2.7,5.85),(3.4,5.1));teaching_arrow(ax,(2.7,4.05),(3.4,4.8))
    teaching_box(ax,7.1,4.5,2.6,.9,"mask future\nthen softmax")
    teaching_arrow(ax,(6.2,4.95),(7.0,4.95))
    teaching_box(ax,.1,1.5,2.5,.9,"source values\ncontent to combine")
    teaching_box(ax,4.8,1.5,3.0,.9,"weighted sum\nretrieved representation")
    teaching_arrow(ax,(2.7,1.95),(4.7,1.95))
    teaching_arrow(ax,(8.4,4.4),(6.6,2.5))
    ax.text(8.6,3.15,"weights",ha="center",color=NAVY,fontsize=12)
    ax.text(5,.3,"Only permitted sources contribute. The output is a vector, not a token prediction.",
            ha="center",color=NAVY,fontsize=11)
    ax.set_title("Follow one query through causal attention",color=NAVY)
    fig.tight_layout();save_figure(fig,"22-attention-route");plt.show()

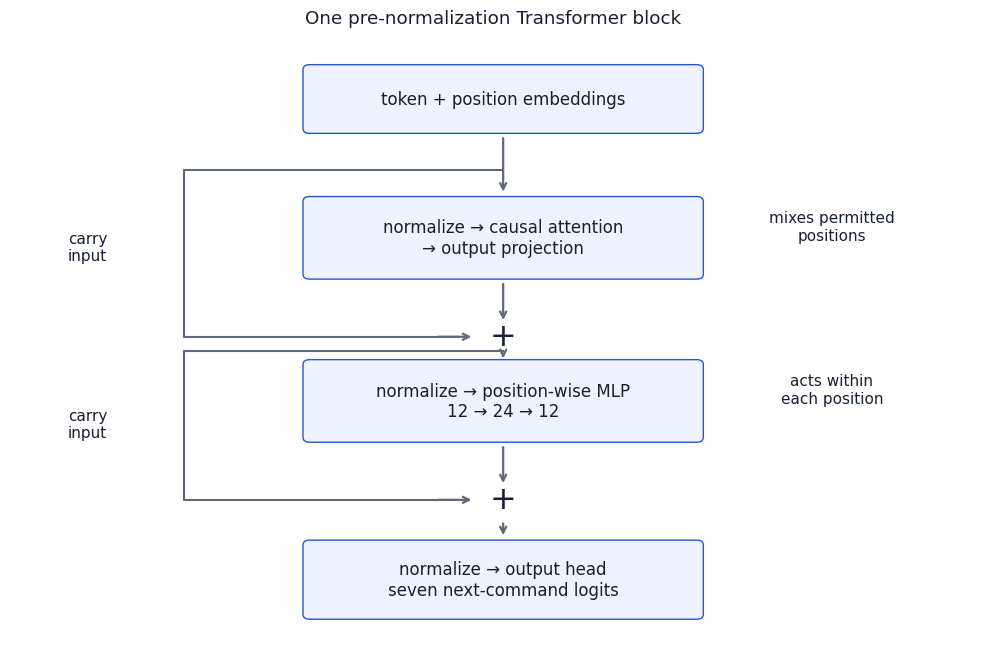
def plot_transformer_block():
    fig,ax=plt.subplots(figsize=(10,6.8));ax.set(xlim=(0,10),ylim=(0,9));ax.axis("off")
    teaching_box(ax,3.1,7.6,4.0,.85,"token + position embeddings")
    teaching_box(ax,3.1,5.5,4.0,1.05,"normalize → causal attention\n→ output projection")
    teaching_box(ax,3.1,3.15,4.0,1.05,"normalize → position-wise MLP\n12 → 24 → 12")
    teaching_box(ax,3.1,.6,4.0,1.0,"normalize → output head\nseven next-command logits")
    teaching_arrow(ax,(5.1,7.5),(5.1,6.65))
    teaching_arrow(ax,(5.1,5.4),(5.1,4.8));ax.text(5.1,4.6,"+",ha="center",va="center",fontsize=23,color=NAVY)
    teaching_arrow(ax,(5.1,4.4),(5.1,4.25))
    teaching_arrow(ax,(5.1,3.05),(5.1,2.45));ax.text(5.1,2.25,"+",ha="center",va="center",fontsize=23,color=NAVY)
    teaching_arrow(ax,(5.1,1.95),(5.1,1.7))
    ax.plot([5.1,1.8,1.8,4.6],[7.0,7.0,4.6,4.6],color=GRAY,lw=1.5)
    teaching_arrow(ax,(4.4,4.6),(4.8,4.6))
    ax.plot([5.1,1.8,1.8,4.6],[4.4,4.4,2.25,2.25],color=GRAY,lw=1.5)
    teaching_arrow(ax,(4.4,2.25),(4.8,2.25))
    ax.text(.8,5.7,"carry\ninput",ha="center",color=NAVY,fontsize=11)
    ax.text(.8,3.15,"carry\ninput",ha="center",color=NAVY,fontsize=11)
    ax.text(8.5,6.0,"mixes permitted\npositions",ha="center",color=NAVY,fontsize=11)
    ax.text(8.5,3.65,"acts within\neach position",ha="center",color=NAVY,fontsize=11)
    ax.set_title("One pre-normalization Transformer block",color=NAVY)
    fig.tight_layout();save_figure(fig,"23-transformer-block-route");plt.show()